
AI Platform Operations Services
Penguin Solutions AI Platform Operations Services delivers specialized expertise and operational accountability to keep AI infrastructure available, productive, and ready to scale.
One Trusted Partner
Simplify operations with one accountable partner across infrastructure, software, vendors, and operations.
Reduced Operational Risk
Reduce risk through AI platform lifecycle management, remediation, governance, and coordinated issue resolution.
Seamless Platform Scaling
Maintain consistent operations when environments, users, workloads, and sites expand as operational requirements grow.
Sustained Return on Investment
Drive greater returns from AI infrastructure through high availability, utilization, and optimized performance.
Our Approach to AI Platform Operations
Whether supporting revenue-generating AI cloud environments, digitally independent sovereign AI programs, or value-creating enterprise AI initiatives, production-level AI infrastructure introduces unique operational challenges.
Efficient AI training and inference platforms span infrastructure, software, operations teams, and technology partners, creating heightened requirements for coordination, visibility, governance, and accountability.
Penguin Solutions applies a proven operational framework that enables organizations to operate, optimize, protect, and govern AI environments throughout their lifecycle.
Production AI environments require continuous operational oversight to maintain platform health and workload availability. Penguin manages day-to-day operations across compute, storage, networking, systems software, and supporting infrastructure while coordinating monitoring, incident response, and remediation activities to keep AI workloads running efficiently.
AI environments are constantly evolving. Workloads change, utilization shifts, and operational requirements grow. Penguin continuously evaluates performance and productive capacity, improving efficiency, increasing utilization, automating routine tasks, and maximizing the value of existing infrastructure investments.
Production AI environments require ongoing coordination across hardware vendors, software providers, upgrades, spare inventory, and lifecycle activities. Penguin reduces operational risk through remediation planning, lifecycle management, OEM engagement, continuity planning, and proactive operational oversight.
AI environments need clear ownership and accountability. Penguin provides operational governance, service reviews, escalation management, reporting, and continuous improvement processes that align platform operations with business requirements while maintaining a single accountable operating partner.

Peak Infrastructure Performance
Penguin Solutions ClusterWareAI™ AI Factory Platform operating system software delivers visibility, automation, and performance insights that allow teams to identify issues early.

Reliable Operating Methods
Proven operational methodologies support consistent monitoring, quick diagnosis and remediation, and streamlined escalation and lifecycle management across the AI environment.

Demonstrated Success
AI Platform Operations Services has proven success operating large-scale AI environments with rapid time to service and highest levels of node availability and SLA achievement.
Deep Technical Expertise for Global Scale & Fast Issue Resolution
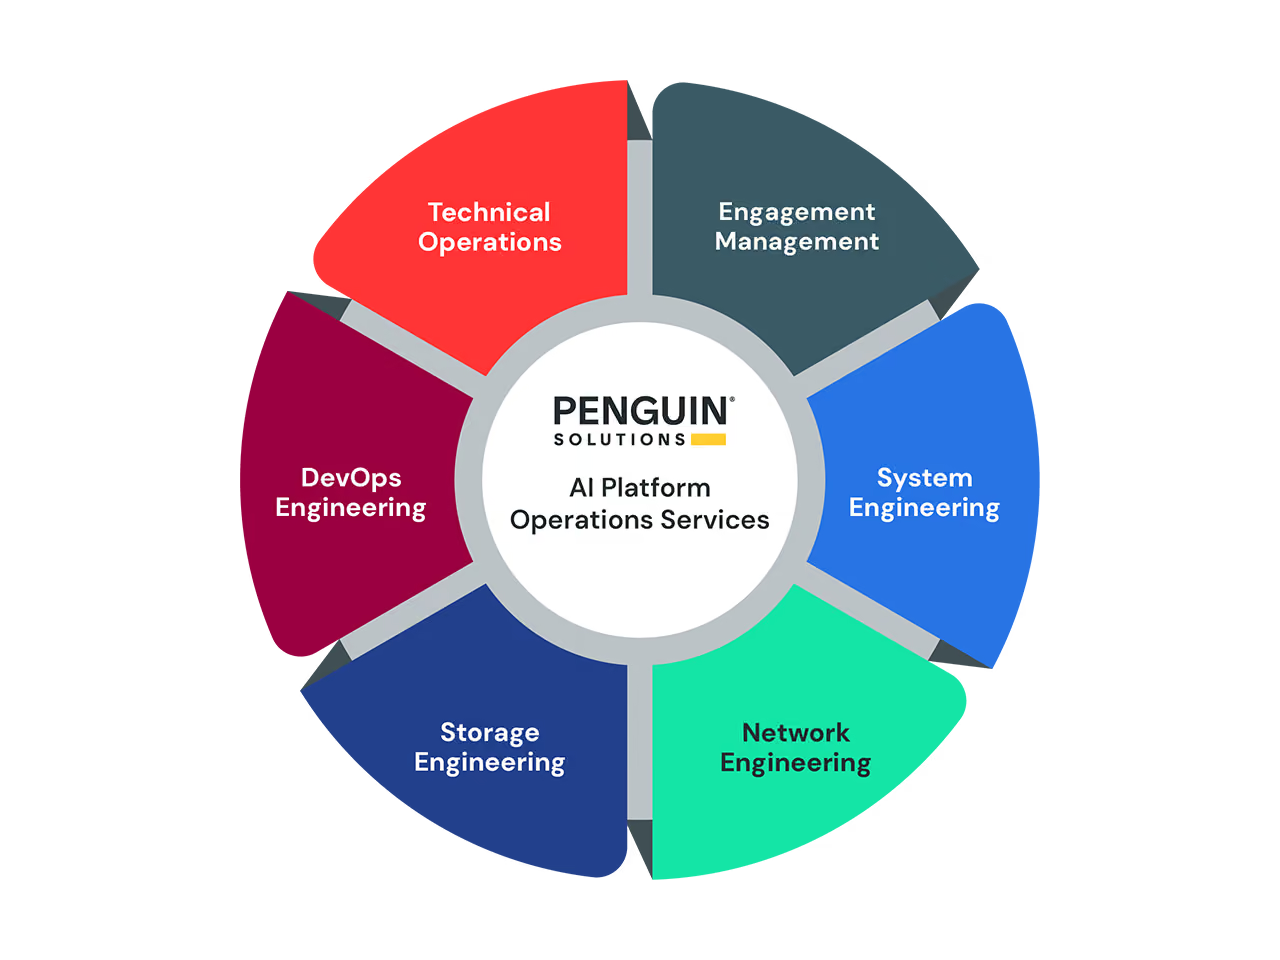
Running AI infrastructure at peak performance and maximum reliability requires deep technical expertise in AI factory operations. Issues impacting production AI environments often span multiple specialized domains, making them difficult to diagnose and requiring coordinated expertise to resolve quickly.
Penguin Solutions operates six Services Centers of Excellence dedicated to these technical domains, connecting specialists worldwide to help customers address complex challenges faster and support Services delivery at global scale.
By connecting the right expertise at the right time, we reduce resolution times, strengthen operational continuity, and maintain platform availability across the full AI environment.
AI Platform Operations
Service Tiers
AI Platform Operations Services offers three flexible service tiers* that align with customer operating models, providing proactive cluster management and clear accountability for availability, performance, and SLA commitments.
Add-on services are also available for environments with additional security, compliance, onsite support, or dark-site operational requirements.
*Service scope, service levels, and responsibilities are defined in the applicable agreement and service description.
Core Operations
Recommended for research and departmental AI environments.
Includes:
- 8x5 operational coverage
- Monitoring and health checks
- Next-business-day response
- Shared operational support
Advanced Operations
Recommended for small-to-mid-sized AI cloud providers and enterprise AI platforms.
Adds:
- 24x7 response for critical incidents
- Cluster optimization & platform engineering
- Dedicated engagement manager
Global Operations
Recommended for larger AI cloud providers, sovereign AI programs, and mission-critical AI environments.
Adds:
- 24x7 onsite technical operations resources; 24x7 follow-the-sun engineering coverage
- Dedicated senior engagement manager
- Full operational accountability
Delivering reliable Day 2 operations for Axe Compute, a rapidly scaling, international neocloud provider, to accelerate delivery of next-generation AI factories. Read the announcement.

Operating SK Telecom’s Haein cluster, one of Korea's largest sovereign AI clusters, with high availability, performance, and operational continuity. Read the full story.


Design AI Infrastructure Services
Accelerate time to value by basing system architectures on a proven set of designs that have been validated at scale in numerous production deployments.

Build AI Infrastructure Services
Achieve high rates of system stability with our in-factory experts who validate all components of the compute cluster including rack integration, network configuration, and burn-in testing.

Deploy AI Infrastructure Services
Drive on-site installations including coordinating with data storage partners, data center staff, system cooling infrastructures, and utilizing ClusterWareAI™ software to validate production readiness.

Talk to the Experts at Penguin Solutions
From AI cloud environments and sovereign AI programs to enterprise AI initiatives, Penguin Solutions AI Platform Operations Services helps organizations operate production AI infrastructure with specialized expertise and operational accountability.