Server room racks
Products > ComputeAI™

Advanced Computing Systems for Faster, More Predictable Deployment

Reduce AI integration complexity, minimize infrastructure design risk, and maintain the flexibility to choose the right technologies for each AI outcome.

Let's Talk
Request Pricing
Advanced Computing Portfolio

Pre-Validated Compute that Accelerates Time-to-Value and Establishes Predictable AI Performance

Deploying and managing AI factories demand significant capital investment and operational precision. Traditional deployments often stall due to challenges with compute integration or design limitations from vendors. When infrastructure is delayed or underutilized, return on investment suffers.

The Penguin Solutions ComputeAI™ portfolio reduces that complexity and risk. With production-ready, pre-validated advanced compute systems, designed to support consistent performance, organizations can spend less time integrating hardware and more time advancing AI initiatives and generating business value.

Drawing on over 25 years of AI and HPC experience, Penguin Solutions validates compute architectures, technology selections, and configurations to provide reliable building blocks for optimized AI factories.

This depth of expertise supports full-stack AI Factory platforms designed to deliver sustained, peak performance for desired AI outcomes.

Architect for Constant Change

Enable disaggregated architectures rather than fixed configurations that scale and adapt as workloads evolve.

Avoid Vendor Lock-In

Leverage systems pre-validated across a broad, multi-vendor ecosystem of accelerators, processors, networking, and cooling.

De-Risk Your Path to Production

Bypass integration bottlenecks with configurations validated by over 25 years of AI and HPC leadership.

The Core Components of ComputeAI

Rather than requiring organizations to choose between rigid, vertically integrated systems and a potentially overwhelming array of configurations, ComputeAI provides validated technologies and configurations aligned to diverse AI workload requirements.

Each system is engineered for efficient operations and reliable performance, allowing teams to build a solid compute foundation for an AI factory environment.
‍

Server room network engineers
  • ComputeAI includes predefined, pre-validated node roles optimized for the AI lifecycle, spanning training, inference, storage, login, scheduler, fabric, and management. These integrated configurations help align infrastructure functions across the environment and reduce the effort required to design and validate the compute layer.

  • ComputeAI is validated across leading accelerator and processor ecosystems, including NVIDIA, AMD, and Intel, giving organizations the flexibility to select silicon options aligned to specific workload requirements within a multi-vendor ecosystem.

  • High-density AI workloads demand adaptable thermal management. ComputeAI supports both air- and liquid-cooled configurations, allowing organizations to align system designs with facility requirements, performance targets, and operational constraints.

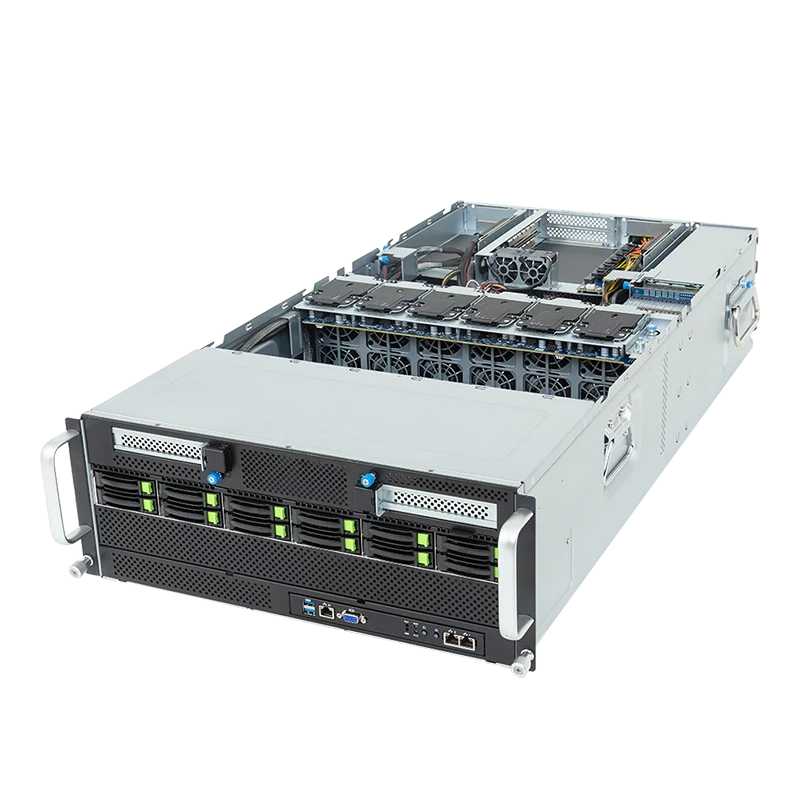
  • ComputeAI Systems

    1U
    Processor
    PCIe Slots
    Memory Capacity
    No items found.
    2U
    Processor
    PCIe Slots
    Memory Capacity
    No items found.
    3U
    Processor
    PCIe Slots
    Memory Capacity
    No items found.
        Model
    GPU
    Processor
    Memory Capacity
  • ComputeAI IEA8-RP6000

    ComputeAI IEA8-RP6000

    Penguin Solutions ComputeAI IEA8-RP6000 is a highly configurable NVIDIA Certified OVX platform designed for AI inference and training, HPC, 3D rendering, deep learning, analytics, and cloud-native applications. The system combines dual Intel® Xeon® 6 processors with support for up to eight GPUs, up to 8 TB of DDR5 memory (32 DIMMs), and extensive PCIe Gen5 expansion to deliver the performance and flexibility required for accelerated computing workloads.

    GPU:
    NVIDIA H200 NVL, RTX Pro 6000 Blackwell Server Edition
    Processor:
    Intel® Xeon® 6 Scalable Processors (Granite Rapids-SP)
    Memory Capacity:

    8TB DDR5 - 6400 MT/s (1DPC), DDR5 - 5200 MT/s (2DPC); MRDIMM: Up to 8000MT/s

    Download Datasheet
  • ComputeAI AEA8-RP6000

    ComputeAI AEA8-RP6000

    Penguin Solutions ComputeAI AEA8-RP6000 is a pre-validated AI infrastructure platform designed for enterprise retrieval-augmented generation (RAG), knowledge assistants, departmental copilots, multimodal inference, and model adaptation workloads. The system combines eight NVIDIA RTX PRO 6000 PCIe GPUs with dual AMD EPYC 9575F processors, 768 GB of total GPU memory, 3 TB (24x 128GB) of DDR5 host memory, and 400 GbE networking to accelerate production AI application deployment while leveraging existing data center infrastructure.

    GPU:
    8x NVIDIA RTX PRO 6000 PCIe GPUs
    Processor:
    2x AMD EPYC™ 9575F Processors
    Memory Capacity:

    3TB DDR5 - 6400 MT/s

    Download Datasheet
  • ComputeAI AEA8-B300

    ComputeAI AEA8-B300

    Penguin Solutions ComputeAI AEA8-B300 combines dual AMD EPYC™ 9005 processors with eight NVIDIA HGX™ B300 GPUs to deliver exceptional performance for AI reasoning, inference, training, and large language model workloads. With up to 6 TB of DDR5 memory, NVIDIA ConnectX®-8 SuperNIC networking, and 1.8 TB/s GPU-to-GPU bandwidth through NVIDIA NVLink™ and NVSwitch™, the platform supports production-scale generative AI and multi-node AI deployments.

    GPU:
    NVIDIA HGX™ B300 with 8 x SXM GPUs
    Processor:
    AMD EPYC™ 9005/9004 Series
    Memory Capacity:

    6TB DDR5 - 6400 MT/s (EPYC 9005), DDR4 - 4800 MT/s (EPYC 9004)

    Download Datasheet
  • ComputeAI IEA8 B300

    ComputeAI IEA8-B300

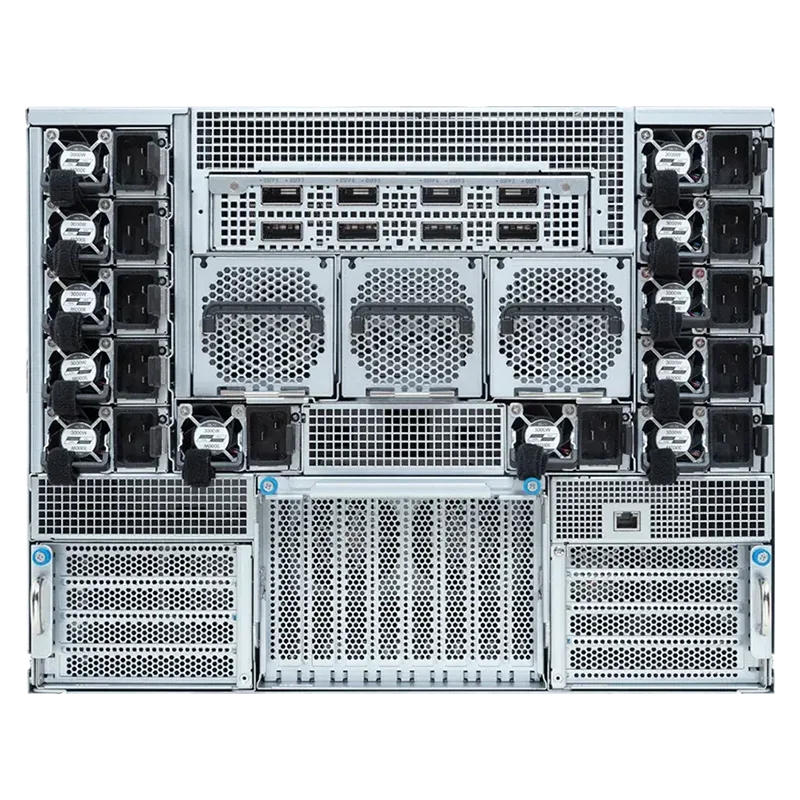
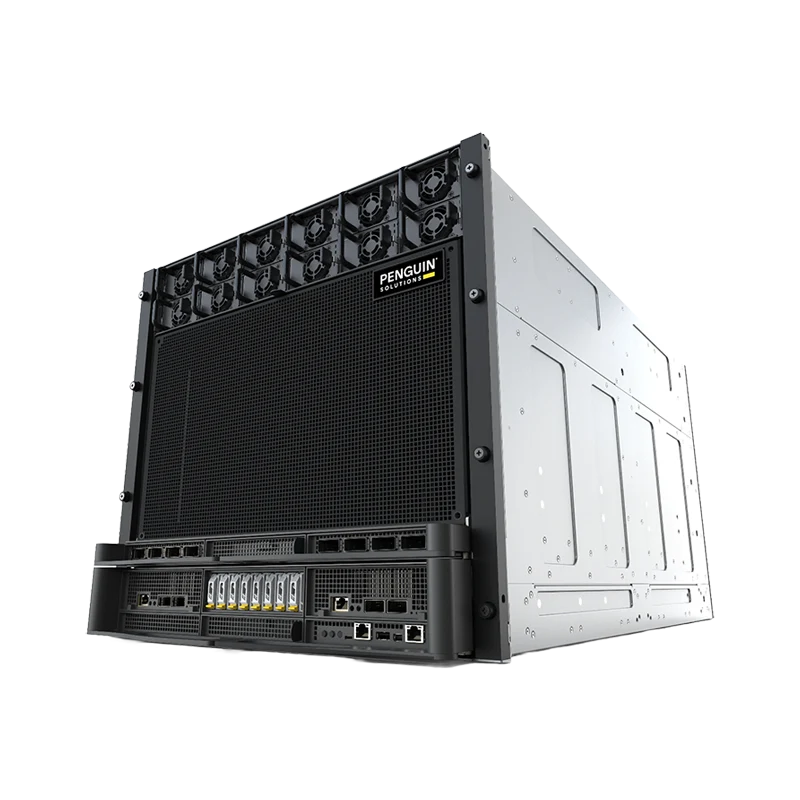
    Penguin Solutions ComputeAI IEA8-B300 is a validated 10U air-cooled NVIDIA HGX B300 platform designed for production AI reasoning, high-concurrency inference, large-context model serving, and advanced fine-tuning workloads. The system combines dual Intel Xeon 6 processors with eight NVIDIA B300 GPUs, 2.3 TB of total GPU memory, 4 TB of host DDR5 memory, and 800 Gb/s scale-out networking to support demanding generative AI and multi-node AI deployments.

    GPU:
    8x NVIDIA B300 GPUs
    Processor:
    Intel® Xeon® 6 Scalable Processors (Granite Rapids-SP)
    Memory Capacity:

    4TB DDR5 (32 DIMMS)

    Download Datasheet
  • ComputeAI NML72-GB300

    ComputeAI NML72-GB300

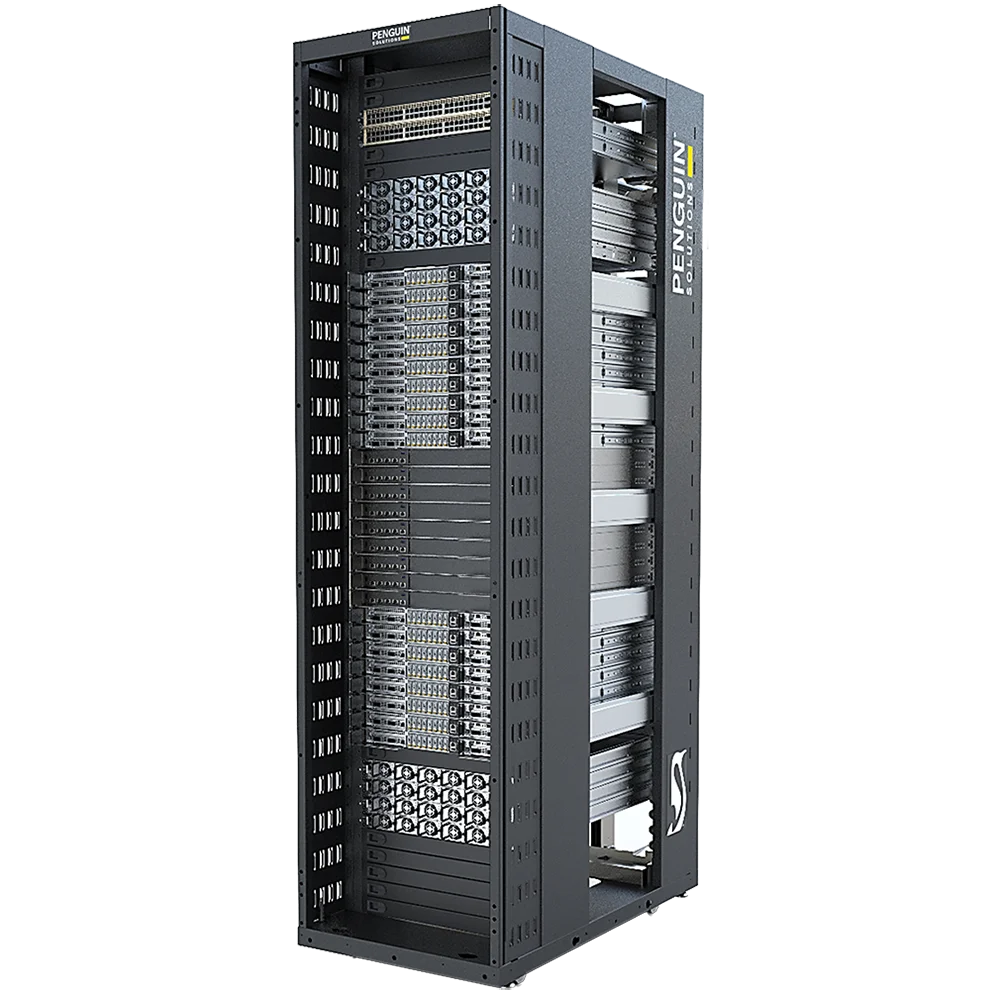
    Penguin Solutions ComputeAI NML72-GB300 is a rack-scale, direct-liquid-cooled NVIDIA GB300 NVL72 system designed for neocloud, sovereign AI, large-model training, AI reasoning, and high-throughput inference services. The validated rack configuration integrates 18 compute trays with 72 NVIDIA B300 GPUs, 36 NVIDIA Grace CPUs, 9 fifth-generation NVLink switch trays, 2.3 TB-class GPU memory per 8-GPU domain scaled to more than 20 TB of total GPU memory per rack, and rack-level NVLink fabric for a single L1 domain.

    GPU:
    72x NVIDIA B300 GPUs
    Processor:
    36× NVIDIA Grace CPUs
    Memory Capacity:

    17.28TB LPDDR5X

    Download Datasheet
  • ComputeAI AEA1-ADMIN

    ComputeAI AEA1-ADMIN

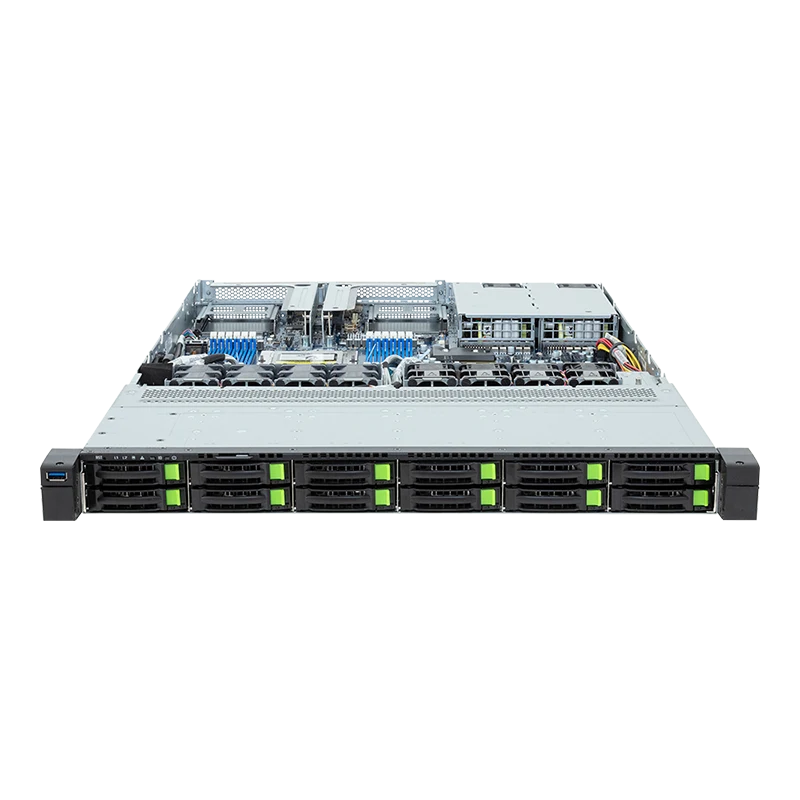
    Penguin Solutions ComputeAI AEA1-ADMIN is a pre-validated management and control-plane platform designed to support AI cluster operations in production AI environments. By integrating infrastructure management services, monitoring capabilities, authentication services, cluster provisioning, and administrative access into a deployment-ready architecture, the platform helps organizations simplify AI operations and maintain consistent infrastructure management at scale.

    GPU:
    N/A
    Processor:
    1x AMD EPYC™ 9355P (32 cores)
    Memory Capacity:

    384GB DDR5 RDIMM

    Download Datasheet
  • ComputeAI AEA1-K8

    ComputeAI AEA1-K8

    Penguin Solutions ComputeAI AEA1-K8 is pre-validated Kubernetes compute infrastructure designed to host AI applications and the CPU-based services that enable production AI environments. By integrating enterprise CPU compute, high-speed networking, scalable storage, and Kubernetes-ready infrastructure into a deployment-ready architecture, the platform supports AI application hosting, enterprise RAG services, AI agents, CPU-based inference services, and production AI operations.

    GPU:
    N/A
    Processor:
    1x AMD EPYC™ 9555P (64 cores)
    Memory Capacity:

    384GB DDR5 RDIMM

    Download Datasheet
  • 5U
    Processor
    PCIe Slots
    Memory Capacity
    No items found.
    5U
    Processor
    PCIe Slots
    Memory Capacity
    No items found.
    5U
    Processor
    PCIe Slots
    Memory Capacity
    No items found.
    Rack of servers
    Request a Callback

    Talk to the Experts at Penguin Solutions

    Connect with the Penguin Solutions team to explore how ComputeAI can help you reduce integration complexity, lower design risk, and accelerate deployment of AI infrastructure.

    Let's Talk